Operating Safely with Delayed and Out-of-Order Data

Executive summary
Most operational dashboards quietly promise something they cannot deliver: that what you see is the complete, current state of the world. In real operations, that promise breaks in a specific and predictable way. Sensor uploads arrive hours after the event. A site with intermittent connectivity delivers a batch at 2 AM containing readings from the previous afternoon. A partner system sends a correction for a record that has already been counted. None of this is bad data, exactly. It is data that arrives after your team has already looked, decided, and acted.
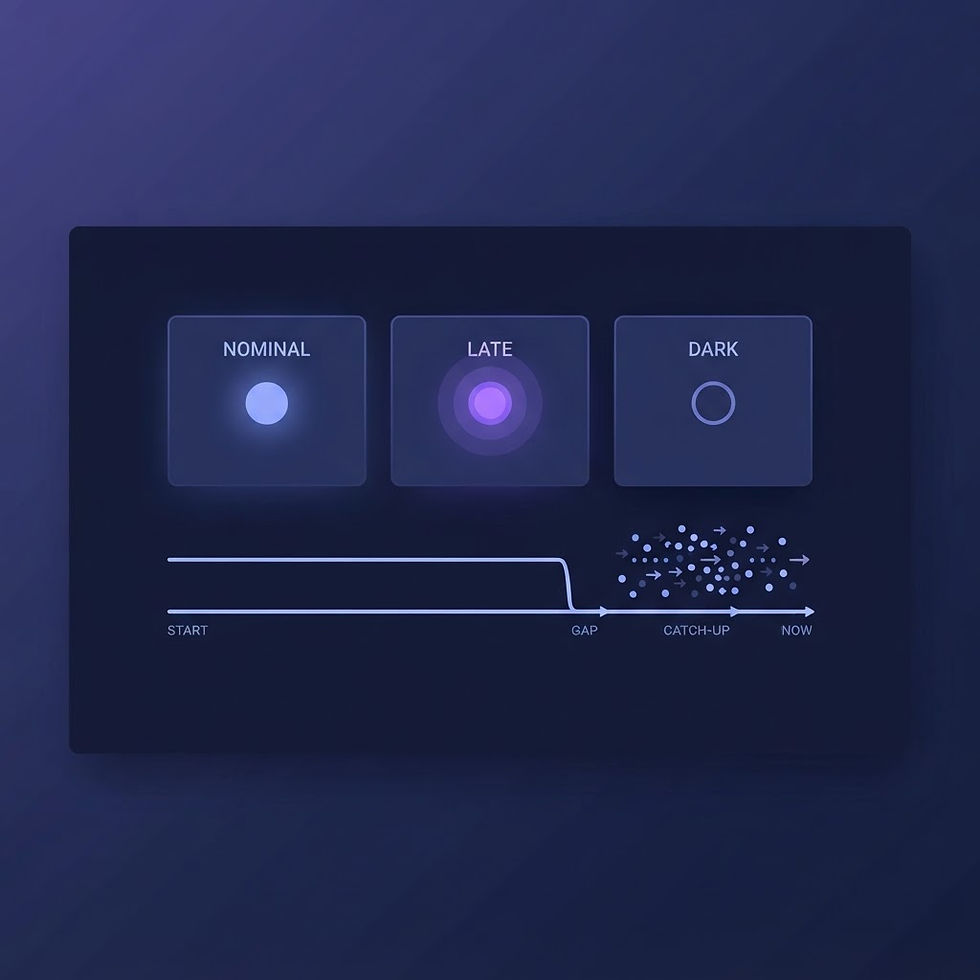
This paper lays out a practical framework for small teams: how to tell the difference between event time (when something actually happened) and arrival time (when your system learned about it), how to decide which decisions can tolerate late corrections and which cannot, and how to design screens so an operator can tell at a glance whether the picture in front of them is complete or still taking shape.
Two clocks, one number
The core concept is simple once you name it. Every operational record carries two timestamps. The event time is when the thing happened in the real world: the meter was read, the part was installed, the status changed. The arrival time is when your system received that record. When connectivity is good and the pipeline is healthy, the two are close enough that nobody notices the difference. That is precisely the danger. The habit of treating them as the same thing is built during the easy weeks, and it fails during the hard ones, when a supervisor asks why yesterday's report no longer matches today's.
The gap between the two clocks is not an error condition. It is a permanent property of distributed operations. A feed that is minutes behind is normal. A feed that is silent for six hours might be normal too, if the site only syncs twice a day. What matters is not eliminating the gap but making it visible at the moment of decision.
The deckplate gap
This is where the deckplate gap shows up in data operations. The operator standing in front of the screen has one job: make a sound decision with the picture available now. But the tool they were handed, the dashboard, presents that picture with the same visual confidence whether it reflects the last twelve hours or the last forty minutes. The interface does not distinguish between "all clear" and "all clear, as far as we know." The operator is left to supply that distinction from memory and experience, which works right up until the day it does not.
The fix is not more data. It is honest labeling. A screen that shows a readiness score should be able to answer, in the same glance, three questions: as of when, how complete, and what could still change.
A practical framework
1. Classify decisions by their tolerance for revision. Some decisions are cheap to reverse: a schedule preview, a forecast, a planning figure. Others are expensive or impossible to reverse once taken: a certification submitted, a part condemned, a shipment released. The first class can run on the best picture available, with corrections applied as they arrive. The second class needs an explicit completeness check before the operator commits. Write down which of your decisions are in which class. Most teams find they have never actually made this list, and that a few high-stakes decisions have been quietly running on unverified data for years.
2. Track a lag number for every source. For each feed or data source, record the typical and worst-case gap between event time and arrival time. This does not require monitoring infrastructure; a simple note reviewed weekly is enough to start. The purpose is to replace vibes with numbers: instead of "that feed is usually pretty fresh," the operator can see "this feed can be up to 24 hours behind."
3. Make completeness a first-class field. Every aggregate, score, or rollup should carry an indicator of how much of its input has actually arrived. If a weekly figure is built from four sites and only three have reported, the figure should say so, not silently present a partial total as the total. The most dangerous number on any screen is a complete-looking result computed from partial inputs.
4. Handle out-of-order arrival explicitly. When a late record lands, decide in advance what happens: does the aggregate recompute, does the correction append, does anyone get told? The worst design is the accidental one, where late data quietly changes a number someone already relied on, with no trace that it moved. A correction that rewrites history without recording the rewrite is worse than the delay itself, because it destroys the ability to explain why a decision was made.
5. Keep the correction visible. When late data changes a picture that was already seen, surface the change. A simple "updated as of" marker, a revision count, or a flag on the affected record is enough. The operator does not need an audit trail worthy of a financial system; they need to know that the number they remember from this morning is not the number on the screen now. If a correction can change a result someone already signed off on, that fact deserves its own visible record, not a silent overwrite.
Putting it into practice
Pilot the framework on one workflow, not the whole system. Pick a single high-value decision and answer the three screen questions for it: as of when, how complete, what could still change. Then apply the test that matters most: could a new team member, looking only at the screen and its labels, tell whether the picture is safe to act on? If they cannot, the labels are not yet doing their job.
Resist the urge to add fields nobody will read. Every indicator must change a real decision or it will be trained to be ignored. And after the first incident where late data surprised someone, fix the labeling rather than adding a warning banner, because the goal is a screen that tells the truth quietly and constantly, not one that shouts after the fact.
Conclusion
Delayed and out-of-order data is not a technical failure to be fixed; it is a permanent condition of real operations to be managed. The teams that handle it well are not the ones with the most sophisticated pipelines, but the ones whose screens admit what they do not yet know. Classify your decisions by their tolerance for revision, label your pictures with as-of and completeness, and keep corrections visible. A modest routine applied consistently beats an elaborate process that exists only on paper.
Disclaimer
This article is for general informational purposes only and does not constitute legal, cybersecurity, workforce, or operational advice. BlueVioletApps LLC is an independent company and is not affiliated with, endorsed by, or sponsored by any federal agency, military branch, or government organization. Always validate requirements with qualified professionals and the responsible authorities for your environment.

Comments