Operational Resilience by Design: Recovery Objectives for Small Mission Teams

Updated: Sep 7
When a software outage occurs during tactical operations or critical administrative workflows, the failure is rarely caused by a shortage of server hardware. More often, it stems from an unexamined assumption that purchasing expensive cloud infrastructure automatically guarantees operational continuity. True resilience is not an off-the-shelf purchase; it is a discipline of honest design, deliberate recovery objectives, and battle-tested restore paths.
Executive Summary
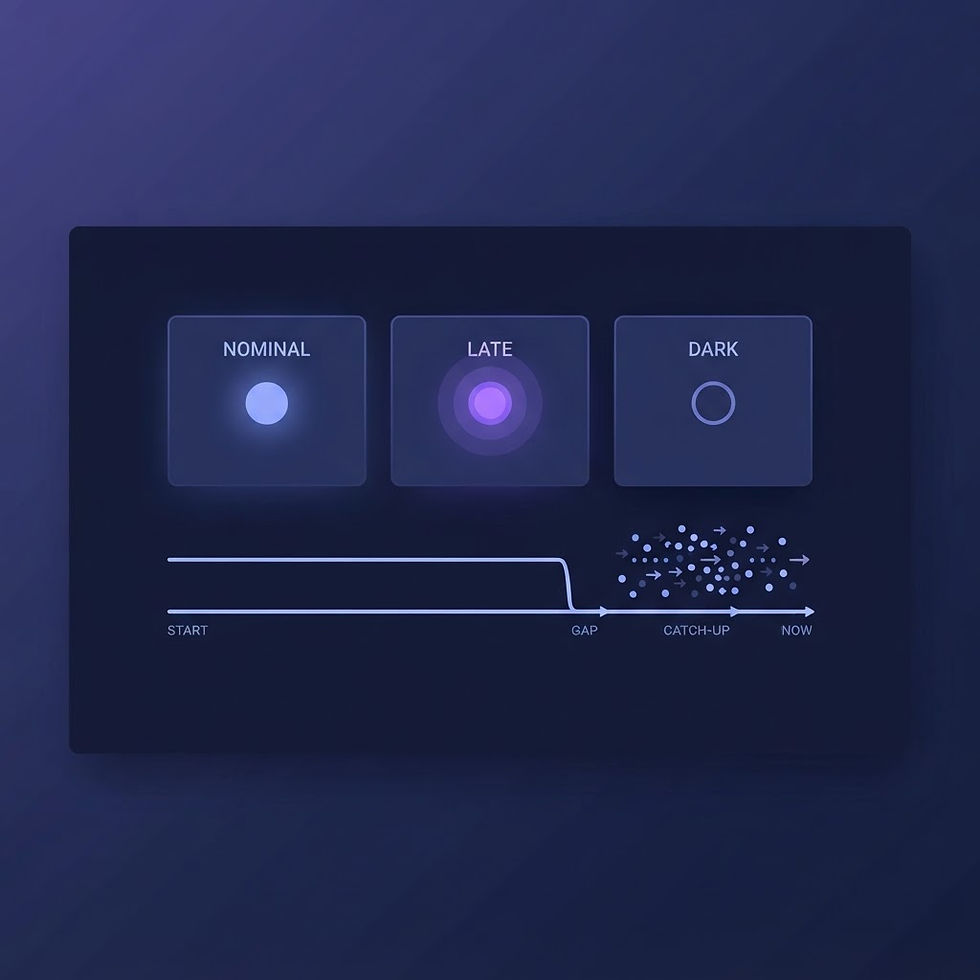
Small mission teams frequently fall victim to the Deckplate Gap—the stark distance between an architecture that looks mission-ready in a vendor demo and one that actually survives unexpected outages at the operational deckplate. When systems crash under real-world stress, teams without clear recovery objectives waste crucial hours debating priorities rather than restoring operational capability. This white paper outlines a practical framework for small software and operational teams to define Recovery Time Objectives (RTO) and Recovery Point Objectives (RPO) tailored to real operational limits. By embedding resilience into software architecture, documenting lightweight restore procedures, and conducting routine recovery drills, small organizations can achieve high availability without enterprise-scale budgets or administrative overhead.
Defining Honest RTO and RPO for Small Teams
In government procurement and defense technology, high availability is frequently framed as a series of nines. Vendors promise 99.999% uptime, implying that software will never fail. In practice, pursuit of theoretical zero-downtime solutions drains engineering resources while masking single points of failure. Small teams must instead ground resilience in two concrete operational metrics: Recovery Time Objective and Recovery Point Objective.
Recovery Time Objective (RTO): The maximum acceptable duration of system downtime following a failure. This metric dictates how quickly a team must restore functional software before operational capability is compromised.
Recovery Point Objective (RPO): The maximum allowable volume of data loss measured in time between the last valid backup and the disruption. This metric determines backup frequency and data replication strategy.
Honest recovery planning requires categorizing software assets based on operational necessity rather than treating all data equally:
Tier 1 (Mission Critical): Core operational databases and command routing systems. Target RTO: under 1 hour. Target RPO: under 15 minutes.
Tier 2 (Operational Support): Status tracking tools, logistics logs, and internal reporting dashboards. Target RTO: under 12 hours. Target RPO: under 4 hours.
Tier 3 (Administrative Records): Archived historical files, annual compliance documentation, and non-urgent media assets. Target RTO: under 48 hours. Target RPO: under 24 hours.
By establishing these thresholds explicitly, small teams avoid over-engineering non-critical systems while ensuring mission-essential data receives dedicated recovery protection.
The Deckplate Gap in High-Availability Architecture
A common trap for small teams is adopting enterprise multi-region cluster replication without the dedicated operations staff required to manage it. On paper, complex distributed architectures appear impervious to regional outages. At the operational deckplate, however, complexity introduces novel failure modes that routinely catch teams off guard during high-tempo operations.
Three primary failure modes expose this architectural gap:
Credential and Key Lockout: Automated failover mechanisms trigger successfully during an outage, but secondary environments remain inaccessible because emergency encryption keys or administrative secrets reside on an isolated local device.
Configuration Drift: Primary and secondary environments diverge over time as daily software patches and configuration tweaks are applied to production without mirror updates to backup infrastructure.
Tactical Bandwidth Bottlenecks: Restoring multi-terabyte database snapshots over tactical satcom or degraded remote connections requires days of transfer time, rendering cloud backups functionally useless during remote operations.
Resilience is not achieved by layering additional cloud services onto a fragile system. It is achieved by stripping away unnecessary moving parts until the recovery path can be executed reliably by a fatigued watchstander at two in the morning.
Designing Stateless Workloads and Isolated Data Stores
To bridge the gap between theoretical availability and deckplate reality, small software teams should adhere to three foundational architectural principles that prioritize simple restoration over continuous complexity.
Externalize Configuration and State
Application servers should remain completely stateless. Environment variables, access keys, and configuration flags must be stored in centralized, version-controlled secret repositories rather than written directly to local server storage. When an application server fails, the deployment pipeline should be capable of spinning up a fresh replacement instance in minutes using automated container orchestration scripts.
Implement Immutable, Append-Only Storage
Database backups should be executed on strict, automated schedules and written to immutable object storage targets. Immutable storage prevents accidental overwrite or malicious encryption by ransomware. Furthermore, teams should maintain off-site cryptographic checksums for every backup artifact to verify data integrity prior to initiating a restore sequence.
Embed Local Caching and Offline Queuing
In disconnected or intermittent network environments, client applications must degrade gracefully. Software interfaces should cache active operational records locally and queue outbound transactions in local encrypted storage. When connectivity drops, operators can continue inputting log entries and status updates. Once network links re-establish, queued payloads sync automatically to primary servers, preserving data continuity without interrupting operator workflow.
The Restore Path: Verification, Documentation, and Game Days
An unverified backup is merely an unconfirmed hypothesis. Software teams routinely discover that automated backup scripts have been failing silently for months only after a catastrophic disk failure occurs. To ensure recovery paths actually work when needed, organizations must establish a rigorous validation routine.
A repeatable recovery verification workflow includes:
Automated Restore Testing: Schedule monthly automated scripts that spin up an isolated staging database, load the latest snapshot, run automated schema consistency checks, and tear down the environment upon success.
Single-Page SOPs: Document emergency recovery steps in a clear, single-page Standard Operating Procedure (SOP). The SOP must list exact command-line steps, secret access paths, and verification commands without assuming prior system memory.
Unannounced Game Days: Conduct quarterly simulated outage exercises where technical leads are prohibited from assisting. A junior team member must restore full system functionality into a clean test environment using only the written SOP and stored credentials.
Measuring recovery velocity during simulated drills reveals hidden procedural friction long before an operational emergency forces an actual recovery effort.
Resilience as an Operational Capability
For federal procurement reviewers and small team leaders, evaluating software resilience requires looking beyond architectural diagrams and marketing claims. True resilience is an operational discipline built into code, validated through practice, and maintained through clear recovery boundaries.
When small mission teams embrace honest recovery objectives, decouple state from application logic, and routinely practice restore paths, they eliminate the Deckplate Gap. They deliver software that remains dependable not only during standard operations, but when real-world disruptions test operational continuity.
Disclaimer: general professional perspectives, not official government or agency policy, not legal advice.

Comments